

AI Embeddings Explainer
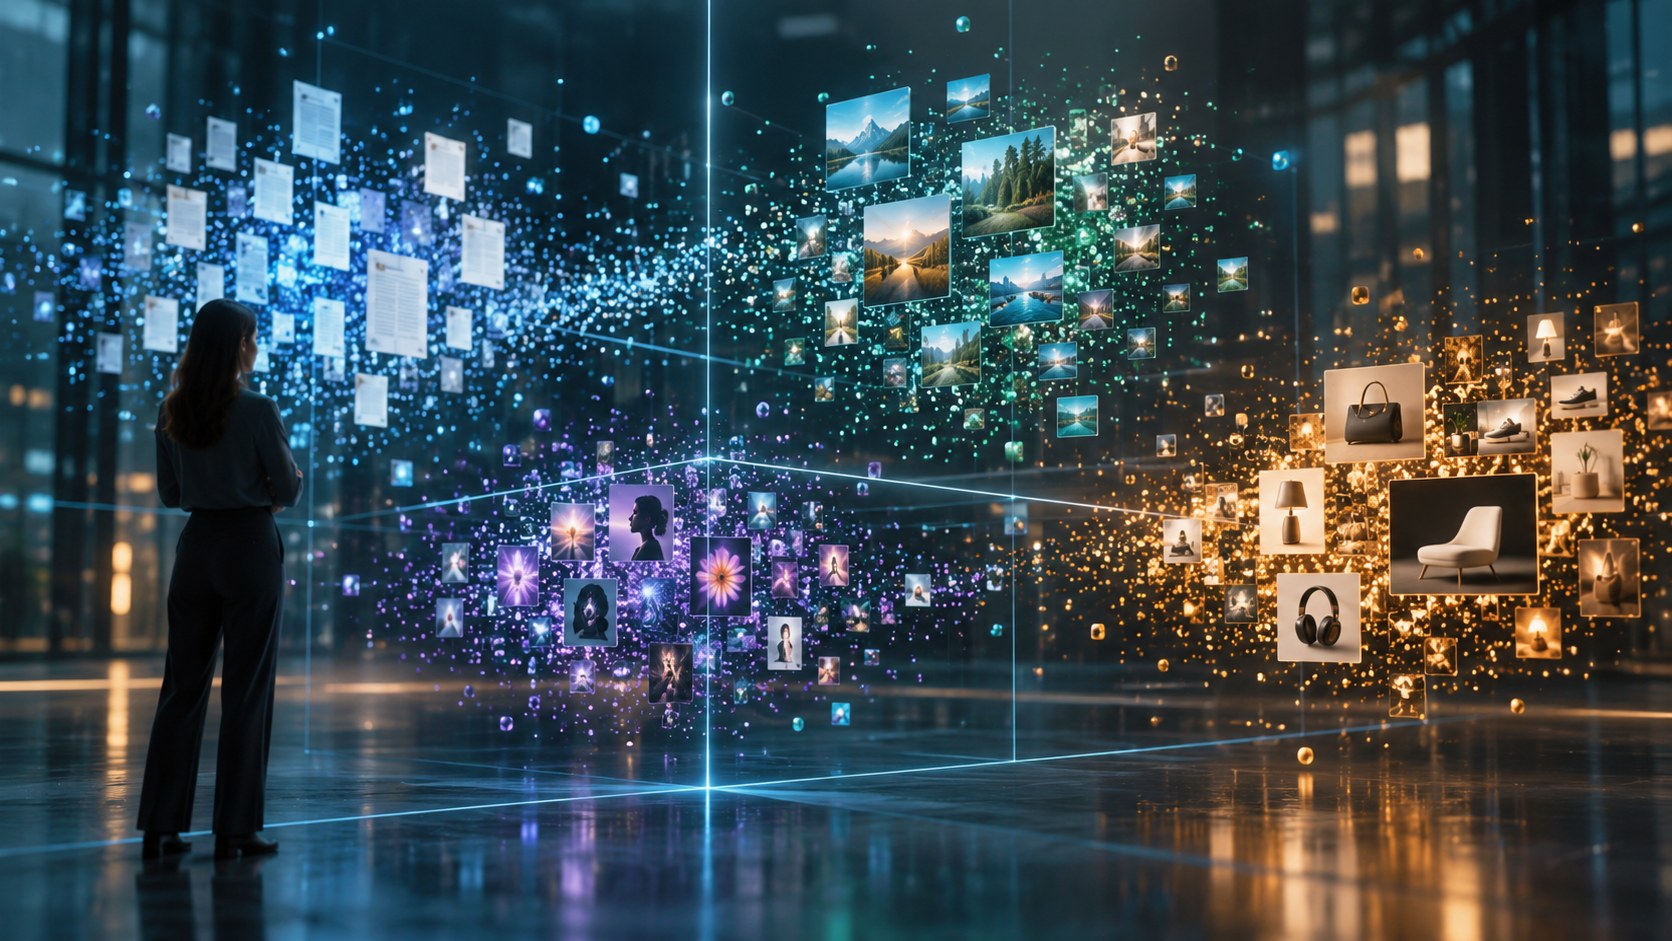
An embedding is a numerical vector that represents an item such as a word, sentence, image, user, or product. An embedding model is trained so that items with related meaning or behavior occupy nearby regions in a multidimensional space. Software can then compare vectors even when the original items do not share the same exact words.
The model maps an input to a fixed-length list of numbers. A distance or similarity measure, such as cosine similarity, estimates how closely two vectors point in the same direction. The individual dimensions usually do not have simple human labels; meaning is distributed across the pattern of values.
Embeddings support semantic search, recommendation, clustering, duplicate detection, classification, and retrieval for language models. A search system can embed both a query and stored passages, then return the nearest passages as possible evidence for a response.
Similarity is not the same as truth or fairness. An embedding inherits the data and objectives used to train it, may perform unevenly across languages or groups, and can place misleading associations close together. Systems should evaluate domain fit, privacy, bias, version changes, and whether nearest neighbors are actually useful for the intended task.
Embeddings convert words, images, or other items into numerical vectors that place related items near one another.
Key terms include embedding, vector, dimension, embedding space, cosine similarity, nearest neighbor, semantic search, clustering and retrieval.
<a href="https://developers.google.com/machine-learning/crash-course/embeddings" target="_blank" rel="noopener noreferrer">Google Machine Learning Crash Course: Embeddings</a> and <a href="https://developers.openai.com/api/docs/guides/embeddings" target="_blank" rel="noopener noreferrer">OpenAI: Vector Embeddings</a> provide the primary references for this explainer.
An embedding model converts each item into a fixed-size vector. Training encourages useful relationships to appear as geometric closeness in that vector space.
Applications compare vectors with a similarity function rather than matching only literal keywords.
Embeddings make semantic search and recommendation efficient, especially when vectors are indexed for fast nearest-neighbor lookup.
They can encode stereotypes, leak sensitive relationships, and drift when the embedding model changes. Evaluation must use real users and real data.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.