

Semi-Supervised Learning Explainer
Semi-supervised learning uses both labeled and unlabeled examples during training. Labels provide direct task supervision, while the larger unlabeled collection helps reveal the structure or variation of the input distribution.
Methods include self-training with pseudo-labels, consistency regularization under data transformations, graph-based label propagation, and generative models. Each relies on assumptions connecting nearby or transformed examples to similar labels.
The approach is attractive when raw data is plentiful but expert annotation is costly, such as images, speech, documents, and scientific measurements. It can outperform a labeled-only baseline when the unlabeled data matches the target task.
Incorrect pseudo-labels can reinforce themselves, and out-of-domain unlabeled data can reduce performance. Evaluation should isolate gains from extra data, tune confidence rules on validation data, and test class balance and domain coverage.
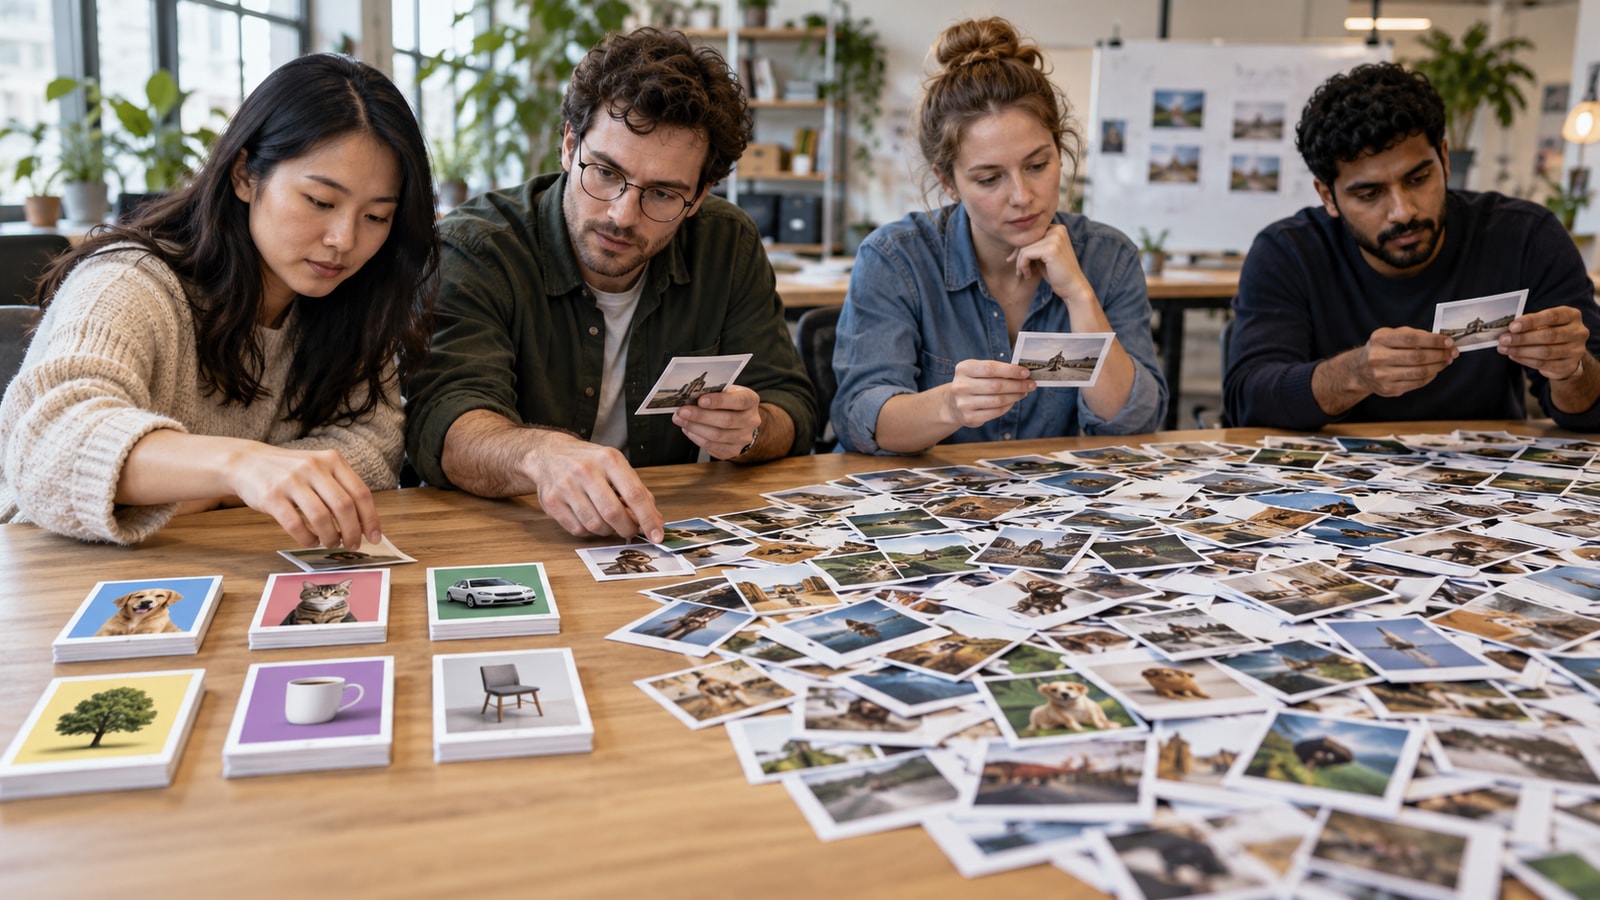
Semi-supervised learning trains with a small labeled dataset and a larger collection of unlabeled examples.
Key terms include labeled data, unlabeled data, pseudo-label, self-training, consistency regularization, label propagation, confidence and domain match.
Unlabeled examples reveal clusters, neighborhoods, transformations, and other structure that the labeled set may not cover.
The algorithm uses that structure to regularize predictions or extend labels beyond the initial examples.
A confident mistake added as a training target may cause the model to become even more confident in similar mistakes.
Thresholds, class balancing, teacher models, and domain checks help control this feedback.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.