

Weak Supervision Explainer
Weak supervision trains models with labels that are cheaper but noisier than carefully hand-annotated ground truth. Signals may come from rules, keyword patterns, existing systems, external databases, crowds, or imperfect predictive models.
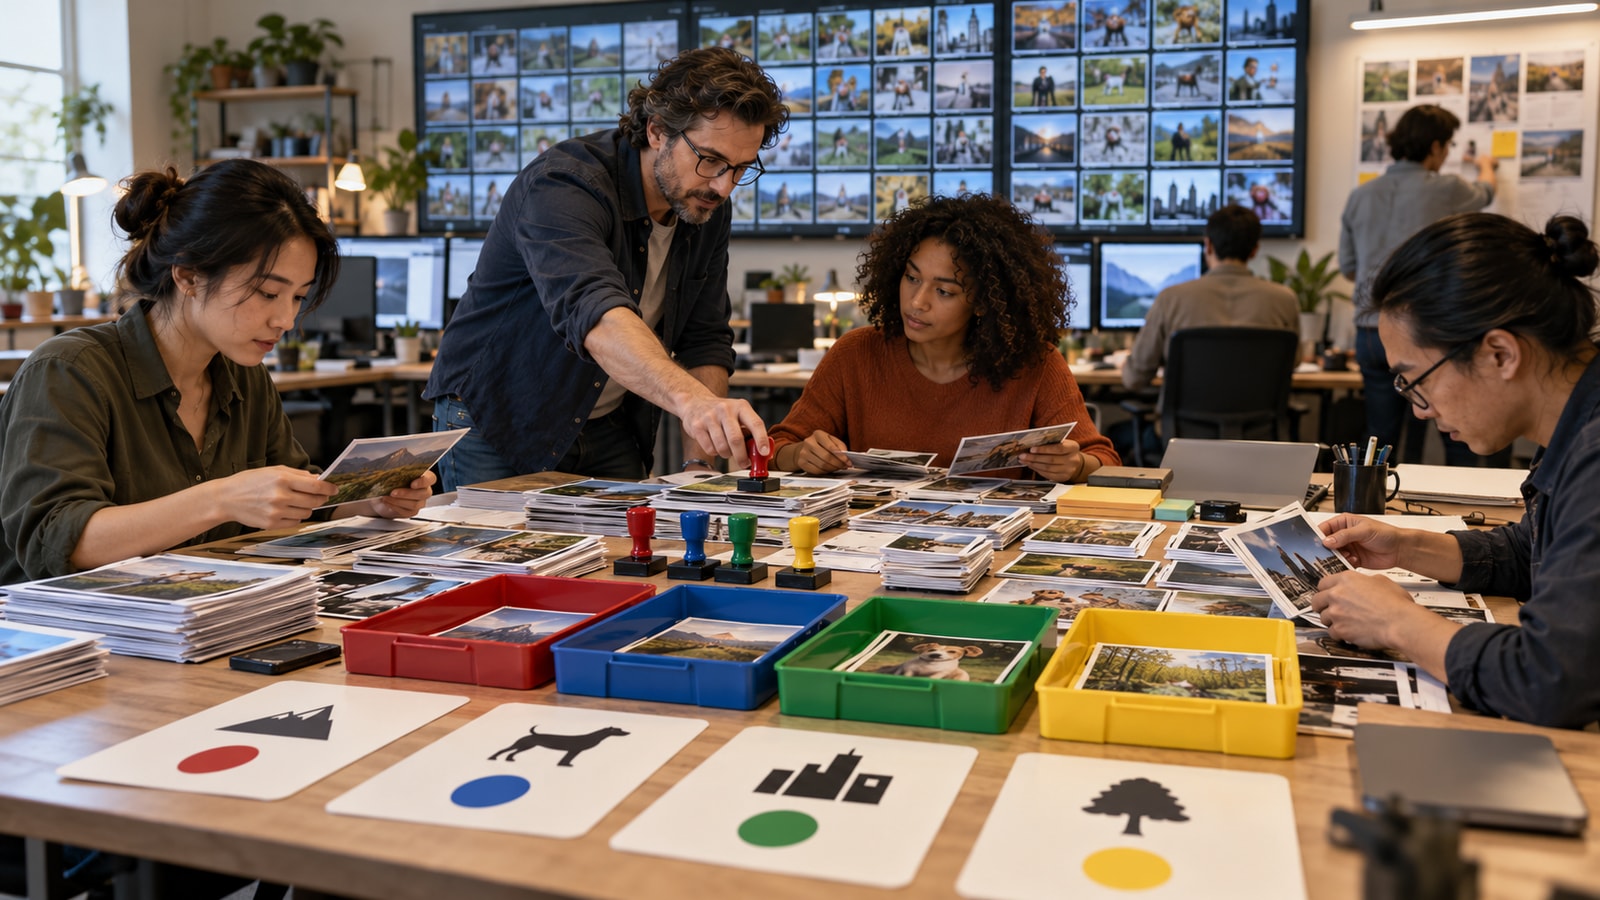
A labeling function applies one such signal and may vote for a class or abstain. A label model can estimate source accuracies and combine overlapping votes into probabilistic training targets for a downstream model.
The method helps teams encode domain knowledge quickly and revise it programmatically. It is useful when expert labels are scarce but several imperfect cues cover meaningful portions of the data.
Weak sources can share the same error, leak the target, or fail on important subgroups. A trusted validation set, coverage and conflict analysis, correlation checks, and clear documentation are necessary before treating scale as a substitute for label quality.
Weak supervision creates approximate training labels from rules, heuristics, distant sources, models, or other noisy signals.
Key terms include labeling function, noisy label, abstention, coverage, conflict, correlation, label model, probabilistic label and ground truth.
Each labeling function covers some examples and may disagree with others, so simple majority voting is not always appropriate.
A label model estimates how the sources behave and produces training targets that express uncertainty.
Several rules derived from the same shortcut may appear independent while repeating one systematic mistake.
Gold validation labels and subgroup tests are needed to reveal shared blind spots and leakage.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.