

Speaker Diarization Explainer
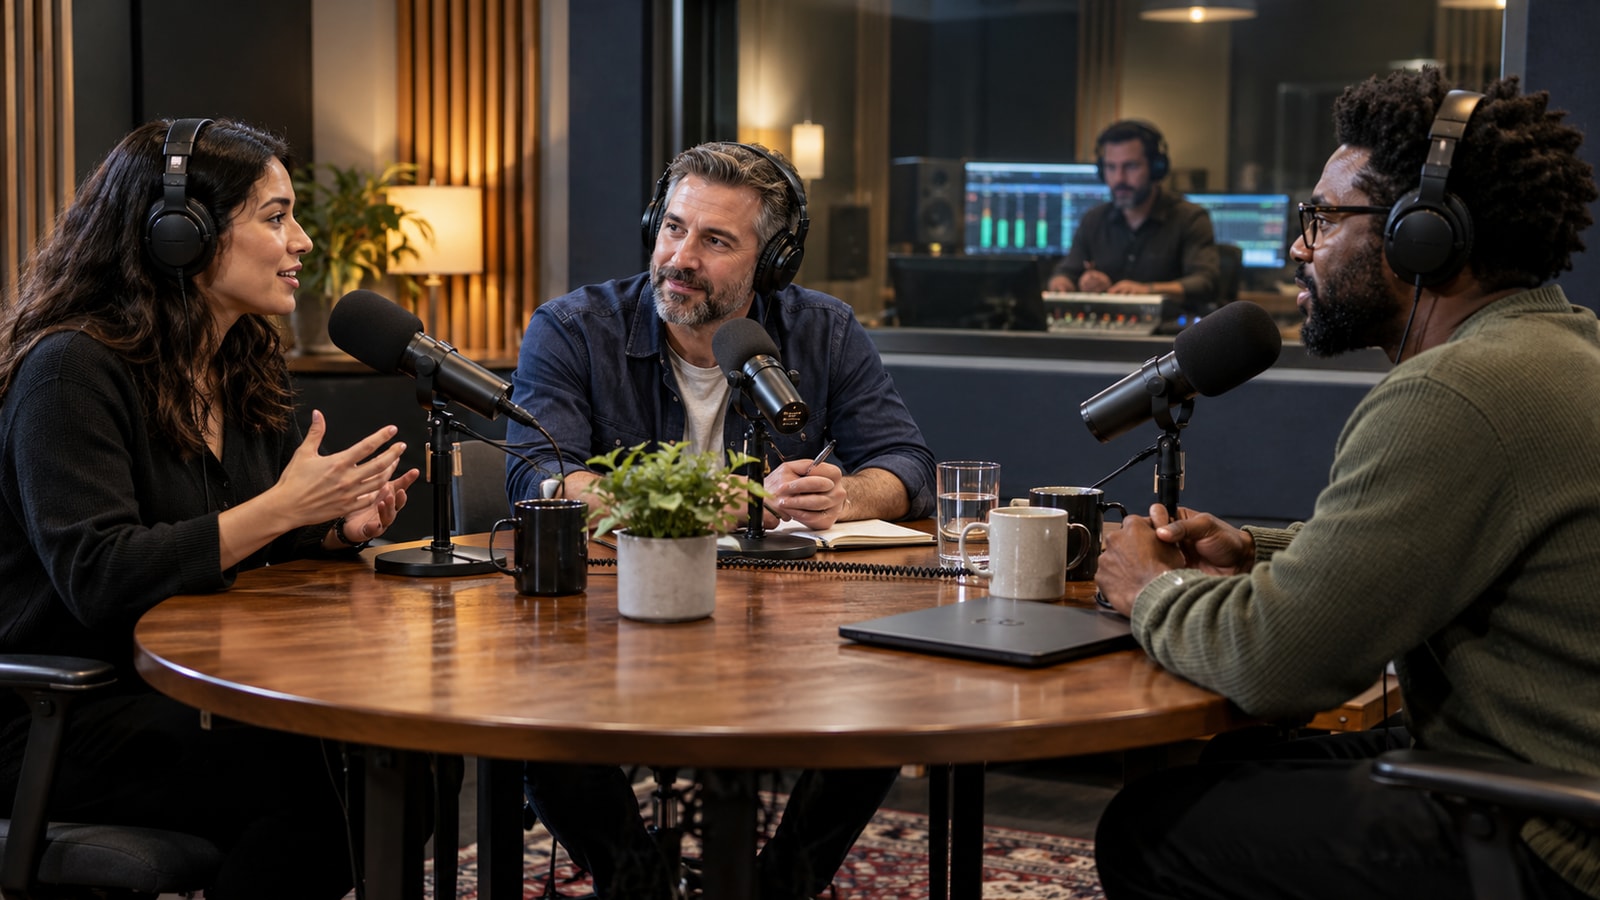
Speaker diarization answers the question of who spoke when in an audio recording. It assigns time segments to distinct speaker labels, usually anonymous labels such as speaker one and speaker two rather than real identities.
A traditional pipeline detects speech, divides it into segments, extracts a speaker representation from each segment, and clusters similar representations. End-to-end systems learn several of these steps jointly and may model overlapping speech directly.
Diarization helps produce meeting transcripts, organize interviews, index broadcasts, analyze call-center conversations, and prepare audio for speech recognition. It is different from speaker recognition, which tries to match a voice to a known identity.
Short turns, interruptions, background noise, similar voices, and two people talking at once create errors. The number of speakers may also be unknown. Evaluation should measure missed speech, false speech, speaker confusion, overlap handling, and behavior across recording conditions.
Speaker diarization divides a recording into segments according to who spoke when, without necessarily knowing each person’s identity.
Key terms include speaker diarization, speech segment, speaker embedding, clustering, overlap, speaker change, diarization error rate and speaker recognition.
Speech regions are assigned to recurring anonymous speaker labels.
Embeddings and clustering connect segments that appear to come from the same voice.
A single time span may contain more than one active speaker.
Noise, short turns, and uncertain speaker counts make simple clustering unreliable.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.