

Named Entity Recognition Explainer
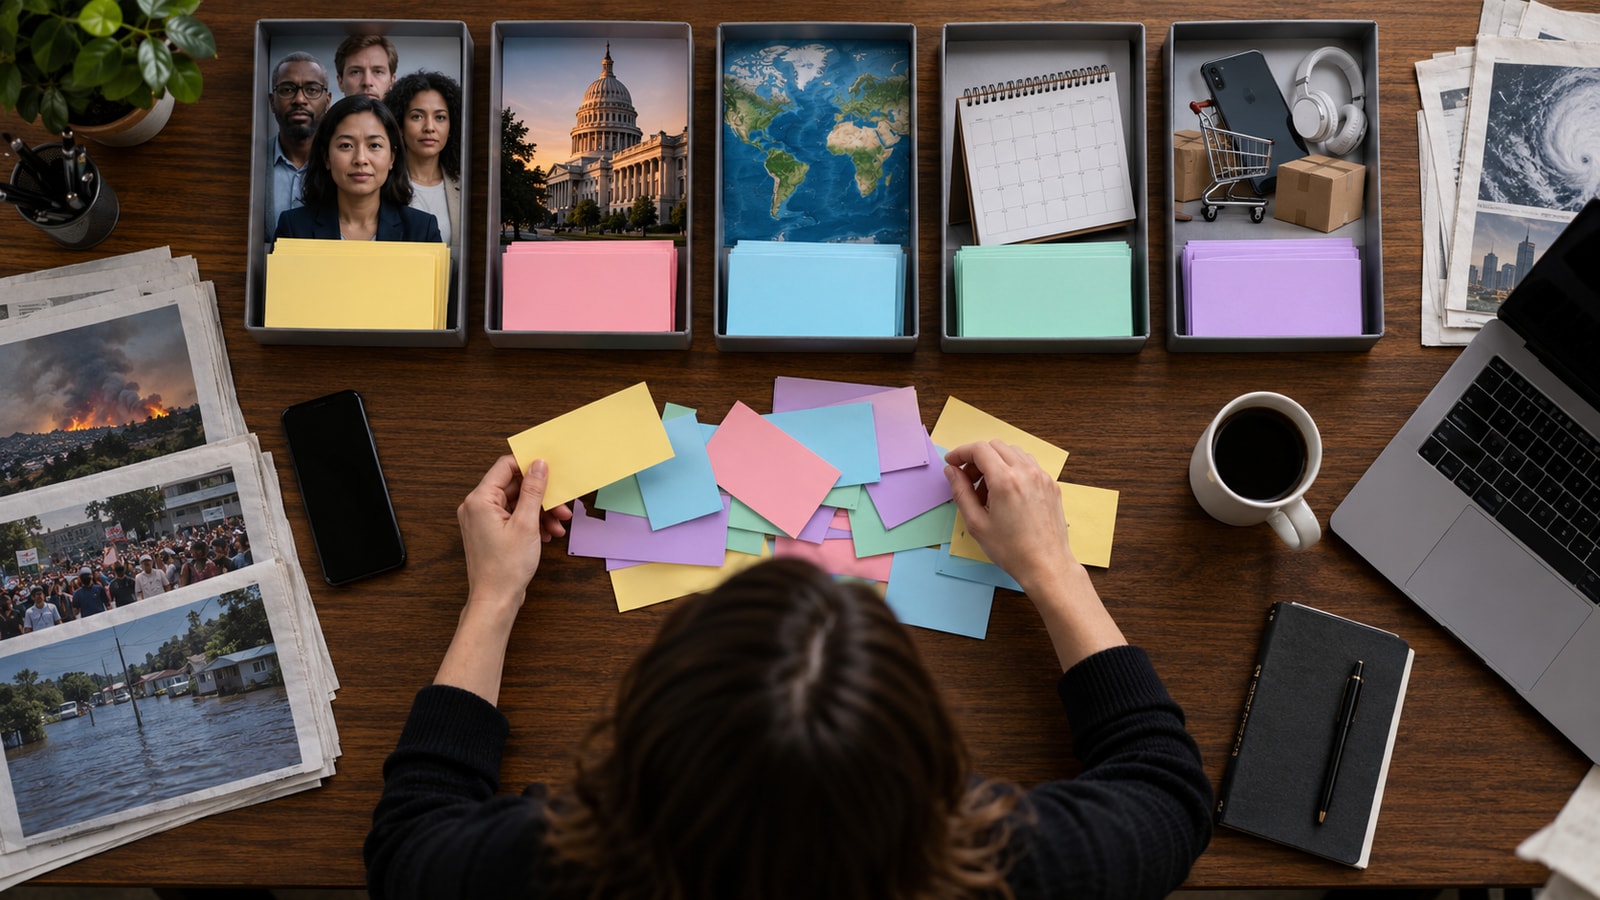
Named entity recognition, or NER, identifies text spans that refer to defined categories such as people, organizations, locations, dates, products, diseases, or chemical compounds. The categories depend on the application and annotation rules.
A model assigns labels to tokens while considering surrounding words. Sequence models capture dependencies between neighboring labels, and pretrained language models provide contextual representations that help distinguish the same word used in different ways.
NER supports search, knowledge-base construction, document routing, news analysis, compliance review, and information extraction in scientific or medical text. Entity linking is a separate next step that connects a mention to a specific database record.
Names may overlap with ordinary words, appear in new forms, or belong to multiple categories. Informal spelling and domain shifts add difficulty. Evaluation should use exact-span and partial-match analysis, per-category results, and tests on recent or specialized language.
Named entity recognition finds spans of text that refer to entities such as people, organizations, places, dates, or products.
Key terms include named entity recognition, entity span, token label, sequence labeling, contextual representation, entity category, entity linking and domain shift.
Context determines whether a word is a name and where the complete mention begins and ends.
Application-specific rules decide which kinds of entities count.
New organizations, products, and people appear faster than static training data can cover them.
Per-category and boundary errors matter more than one overall accuracy number.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.