

Multimodal AI Explainer
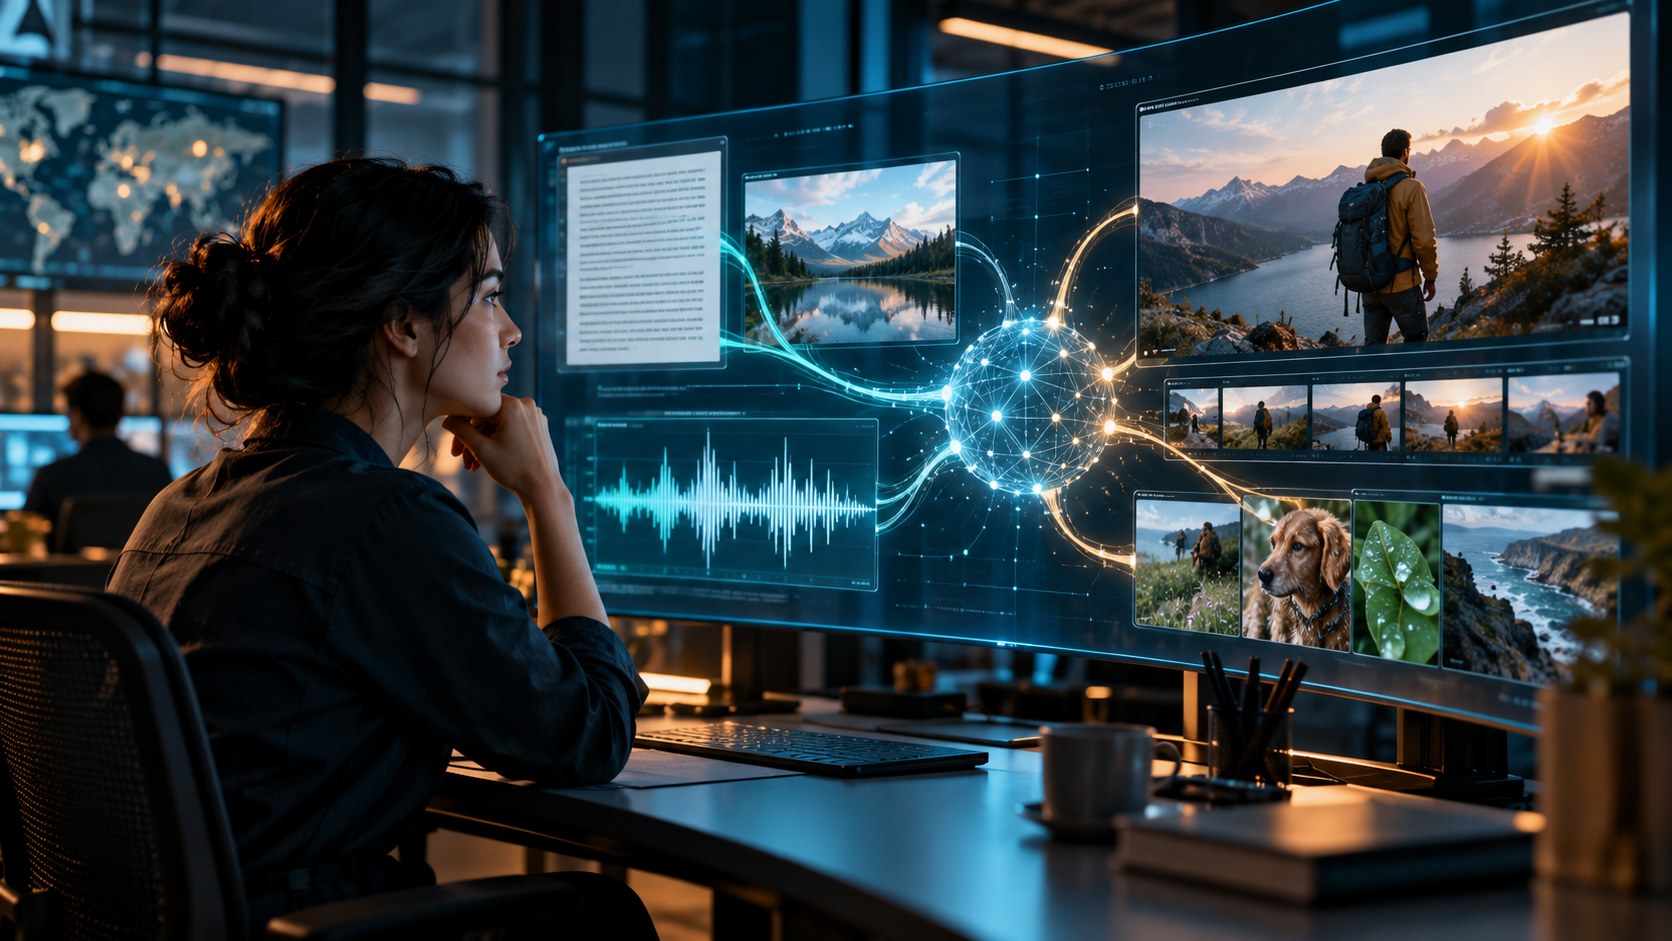
Multimodal AI is designed to process or generate more than one type of data, such as text, images, audio, video, or sensor readings. A system might answer questions about a photograph, create an image from a description, transcribe speech and summarize it, or combine camera and language input to guide a robot.
Different input types begin as different raw signals, so the system uses specialized encoders or tokenization methods to turn them into compatible internal representations. A shared model or connected components then align relationships across modes—for example, linking a region of an image with the words that describe it.
Multimodality can provide context that one channel lacks. Text can name a goal, an image can show the situation, and audio can reveal timing or tone. This supports accessibility, search, media analysis, document understanding, creative tools, and assistants that interact with the physical world.
Combining modes also combines risks. The system may misread a chart, overlook an object, mistranscribe speech, or invent a relationship between inputs. Images and audio can carry sensitive information or be manipulated. Reliable products need modality-specific tests, provenance checks, privacy controls, and clear disclosure of what the model actually received.
Multimodal AI works with more than one kind of data, such as text, images, audio, video, or sensor signals.
Key terms include modality, multimodal model, encoder, representation, alignment, vision-language model, speech recognition, generation and grounding.
<a href="https://developers.google.com/solutions/ai-images" target="_blank" rel="noopener noreferrer">Google: Multimodal Text and Image Prompting</a> and <a href="https://arxiv.org/abs/2312.11805" target="_blank" rel="noopener noreferrer">Gemini: A Family of Highly Capable Multimodal Models</a> provide the primary references for this explainer.
Encoders convert each data type into numerical representations. The model learns relationships across those representations so information in one mode can guide another.
Architectures may join modes early, combine them in shared layers, or connect specialized models through a larger system.
A model can be strong with text yet weak on a small visual detail, or accurately transcribe words while missing a speaker's meaning.
Testing should isolate each modality and their interaction, including accessibility, manipulation, privacy, and ambiguous evidence.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.