

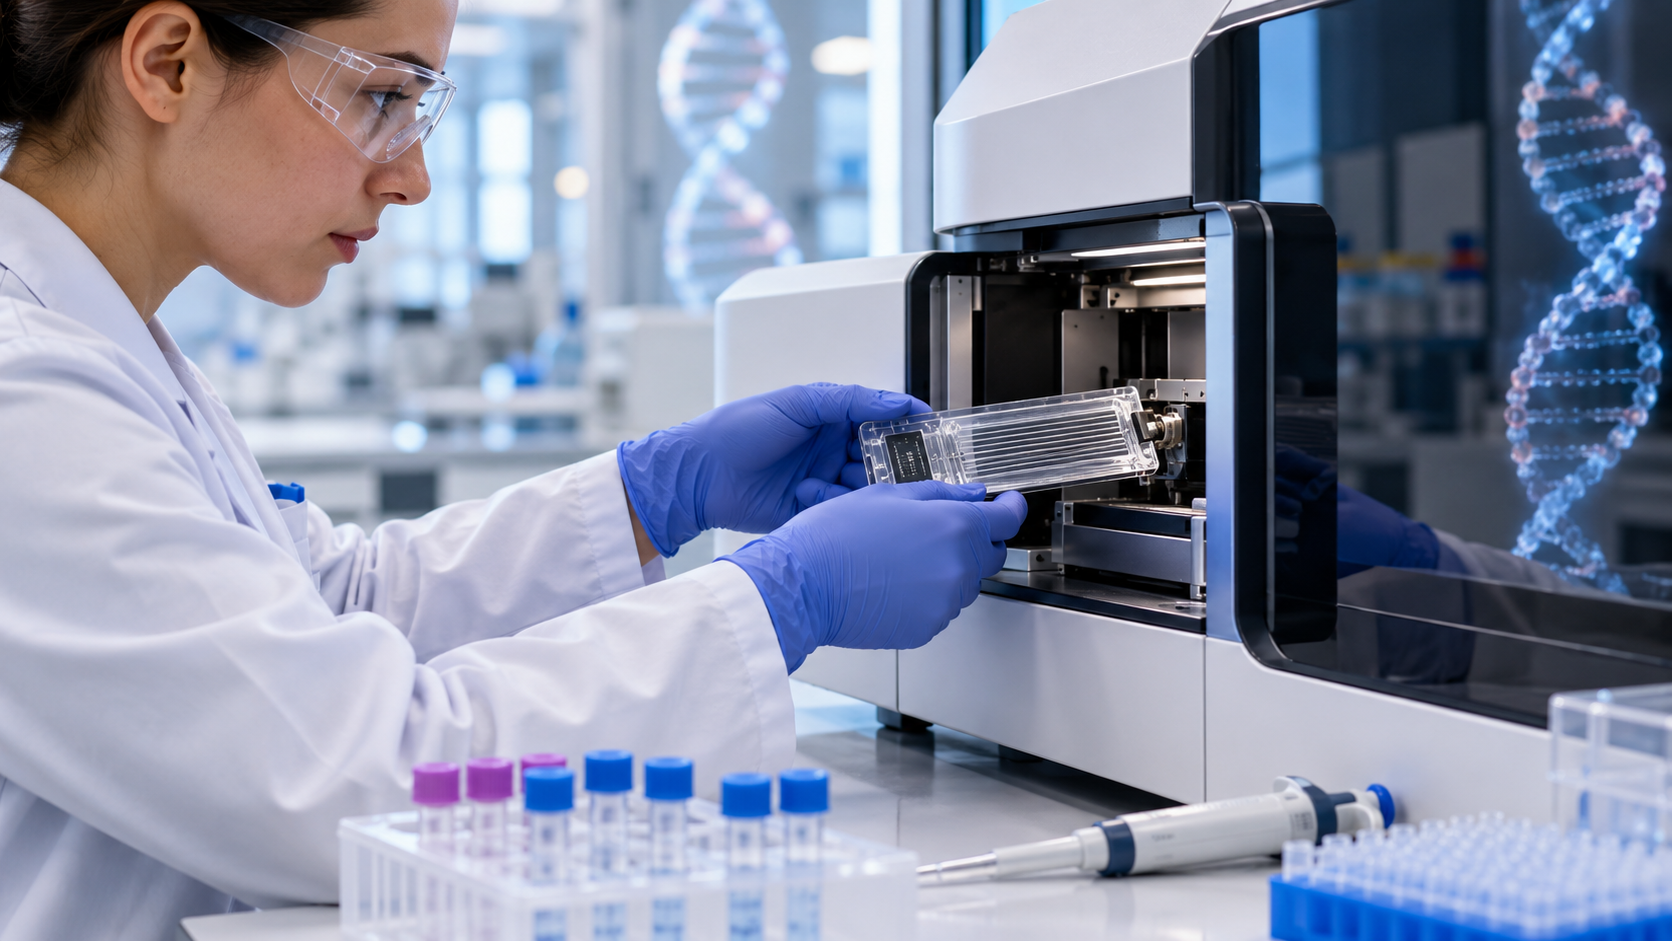
How DNA Sequencing Reads Genetic Information Explainer
DNA sequencing determines the order of the four nucleotide bases—adenine, cytosine, guanine, and thymine—along a DNA molecule. The instrument does not read letters printed on a strand. It measures light, electrical current, chemical incorporation, or another physical signal whose pattern depends on which base is present, then software translates the signal into a sequence.
A sample is first collected and DNA is purified. Many methods break long chromosomes into smaller fragments and attach known adapter sequences. Selected fragments may be amplified, although some technologies read single molecules. Preparing a library controls which DNA enters the instrument and can introduce bias if some fragments are lost or copied more easily than others.
In sequencing by synthesis, a polymerase copies template DNA and base additions generate distinguishable signals. Other platforms monitor changes as DNA passes through a nanopore or use different chemistries. Each produces reads with characteristic length, speed, cost, and error patterns. No technology is best for every genome, medical question, or field sample.
Computers assign a base and quality score at each position. Short reads can be aligned to a reference genome or assembled by finding overlaps. Repetitive regions are difficult because identical pieces fit in many locations, while long reads can bridge more repeats. Paired reads and maps of larger structures add information about how fragments connect.
Coverage describes how many reads support a position. Greater depth can distinguish true variants from random error and reveal mixtures of cells or organisms, but it cannot correct every systematic bias. Contamination, sample swaps, amplification artifacts, and incomplete reference genomes can all mislead. Confirmatory methods are important for high-stakes results.
Sequencing supports diagnosis, outbreak tracking, ancestry research, conservation, agriculture, and basic biology. A sequence alone does not fully explain function or health. Many variants have uncertain effects, gene regulation depends on context, and privacy matters because a genome can identify an individual and reveal information about relatives. Reading bases is the first analytical step, not the final interpretation.
Sequencers convert base-dependent optical, chemical, or electrical signals into an ordered string of A, C, G, and T.
Purification, fragmentation, adapters, and optional amplification create a sequencing library.
Platforms trade read length, accuracy, speed, throughput, and cost in different ways.
Software base-calls the raw signal and aligns reads to a reference or assembles overlaps into longer sequences.
Coverage and quality scores quantify support, while repeats, contamination, and systematic bias remain challenges.
Biological and medical meaning requires additional evidence, careful interpretation, and protection of genetic privacy.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.