

Pipeline Parallelism Explainer
Pipeline parallelism splits a neural network into consecutive stages and assigns each stage to a different device. Activations move forward from stage to stage, while gradients move backward during training.
A training batch is divided into microbatches so multiple stages can work at the same time on different examples. Scheduling forward and backward passes carefully reduces the idle period known as the pipeline bubble.
The approach helps fit deep models across devices and can be combined with tensor and data parallelism. It is most effective when stages have balanced computation and communication costs.
Uneven layers create slow stages that limit the whole pipeline. More stages can increase bubble overhead, activation transfers, and scheduling complexity. Evaluation should include memory, throughput, latency, balance, microbatch count, and failure recovery.
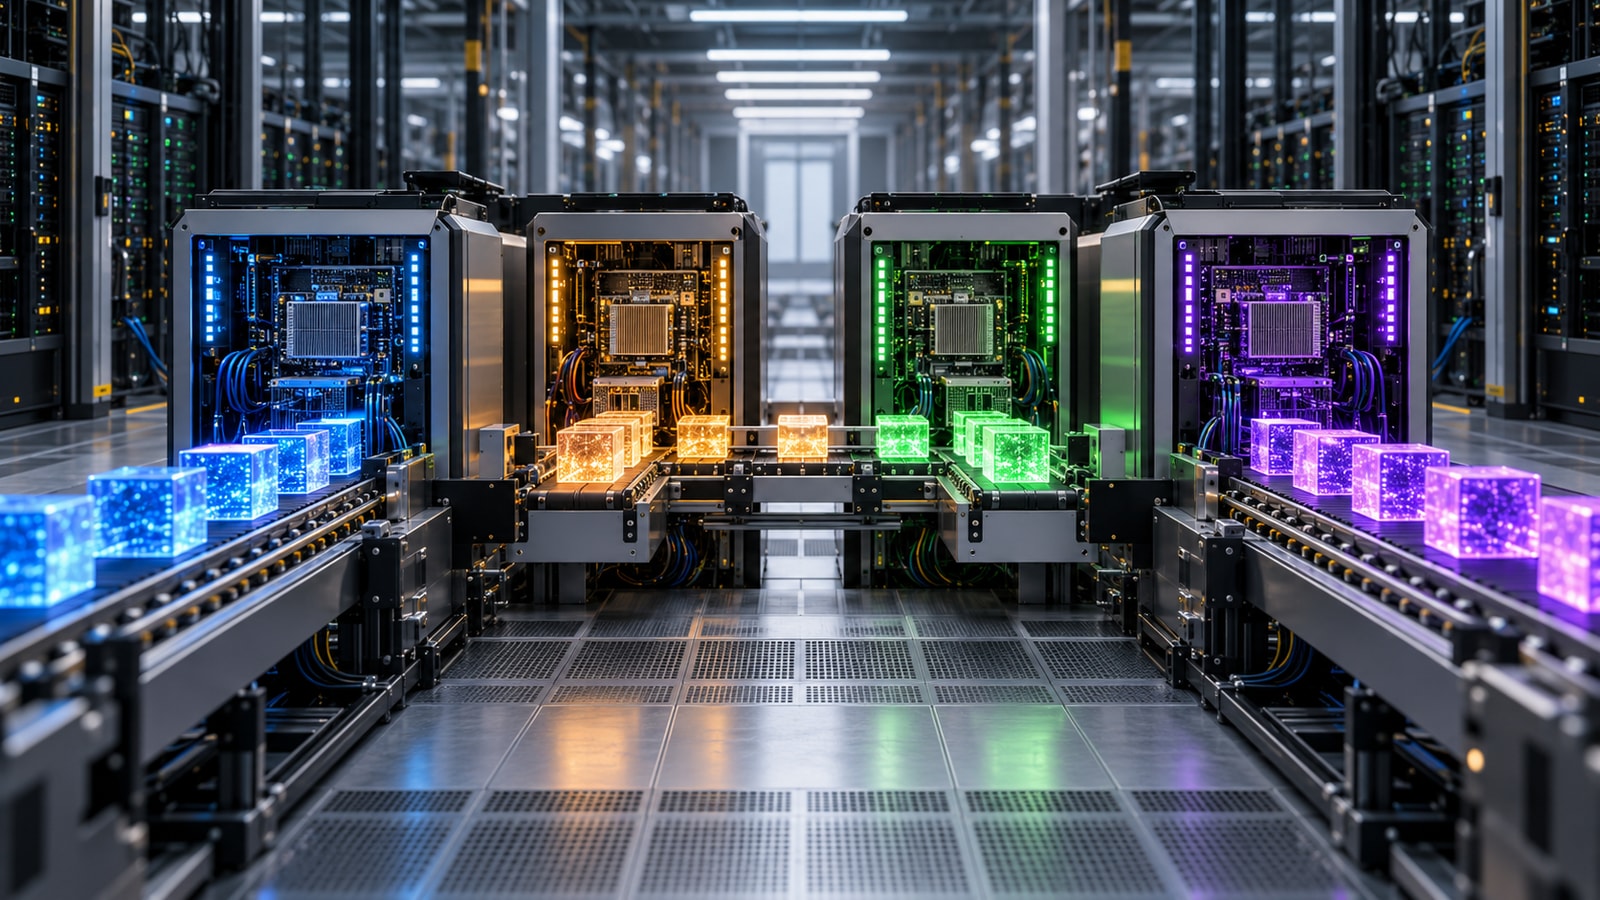
Pipeline parallelism places consecutive model stages on different devices and moves microbatches through them like an assembly line.
Key terms include pipeline parallelism, stage, microbatch, activation, gradient, pipeline bubble, schedule, load balance and throughput.
Each device owns consecutive layers and passes activations to the next stage.
Overlapping microbatches keeps several stages active at once.
Unbalanced computation causes faster stages to wait.
Bubble size, transfers, and microbatch scheduling determine efficiency.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.