

Data Parallelism Explainer
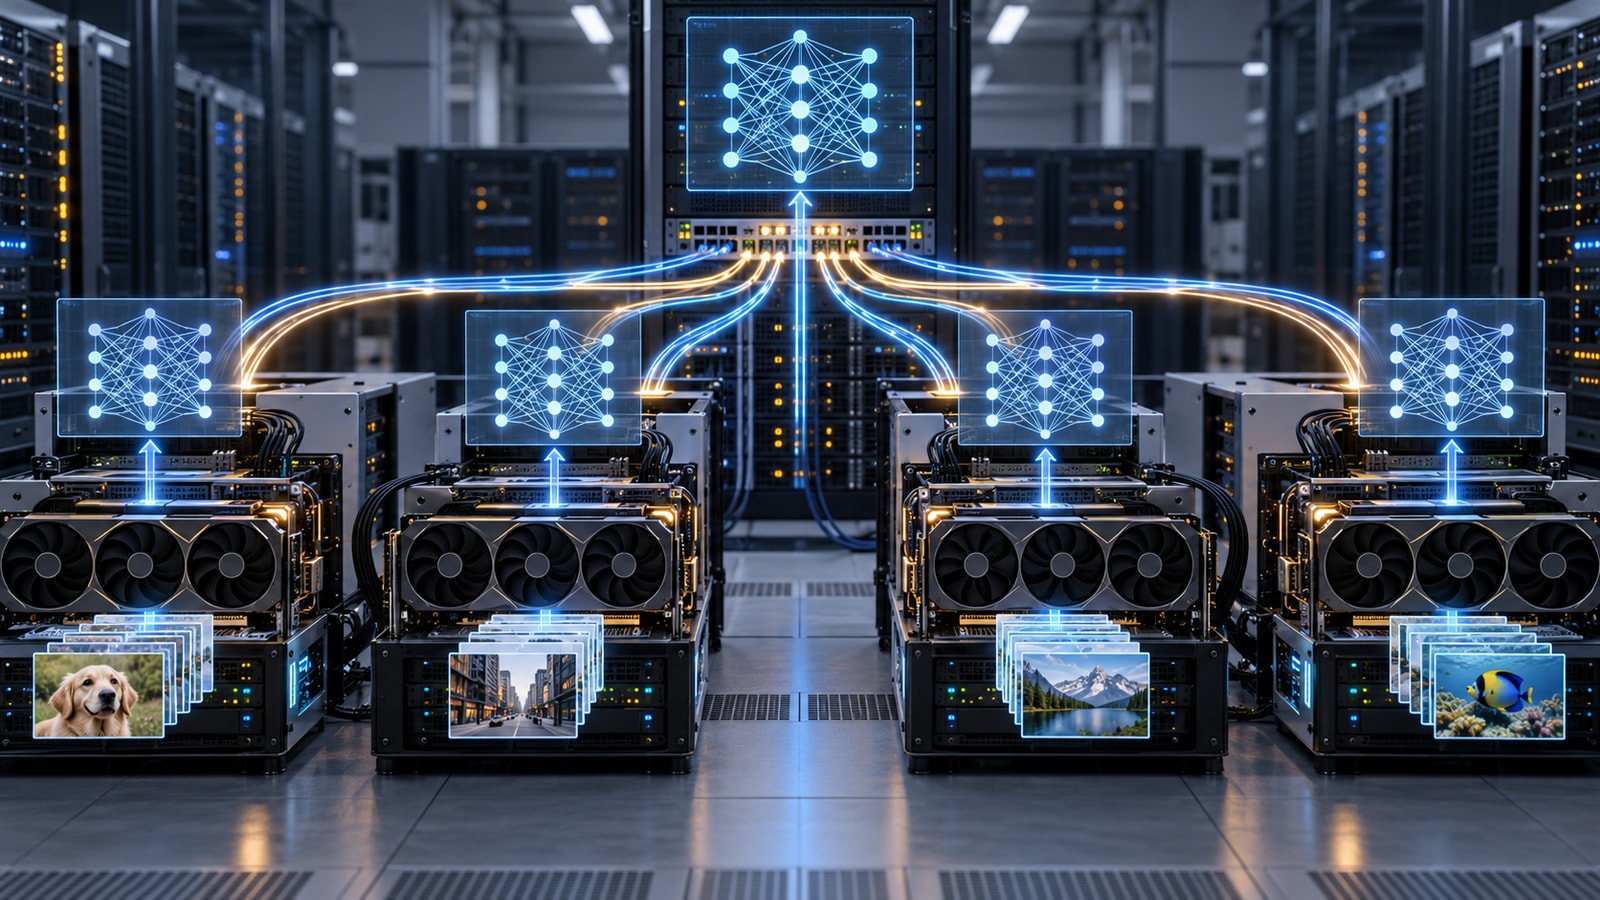
Data parallelism replicates a model across multiple devices and sends each device a different subset of the training data. Every replica computes gradients from its local examples.
The gradients are aggregated, commonly with an all-reduce operation, so all replicas apply a consistent parameter update. Distributed implementations overlap some communication with backward computation to reduce waiting.
The technique increases the effective batch throughput and is a standard way to scale training when a model fits on each device. It can be combined with sharding methods when parameters or optimizer states are too large.
Very large global batches can change optimization and require learning-rate or schedule adjustments. Slow links, straggling workers, and small per-device batches reduce efficiency. Scaling studies should report training quality, time, communication, and hardware utilization.
Data parallelism gives multiple devices copies of a model and trains each copy on a different portion of the batch before synchronizing updates.
Key terms include data parallelism, model replica, local batch, global batch, gradient, all-reduce, synchronization, worker and scaling.
Each device runs the same model on its own slice of the batch.
Aggregated gradients keep model parameters synchronized after each step.
More devices can increase throughput while reducing the number of updates per example.
Learning schedules, communication, and statistical efficiency must be tuned together.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.