

“The model we study can be interpreted as a broad, abstract extension of the well-studied on-line prediction model to a general decision-theoretic setting.”
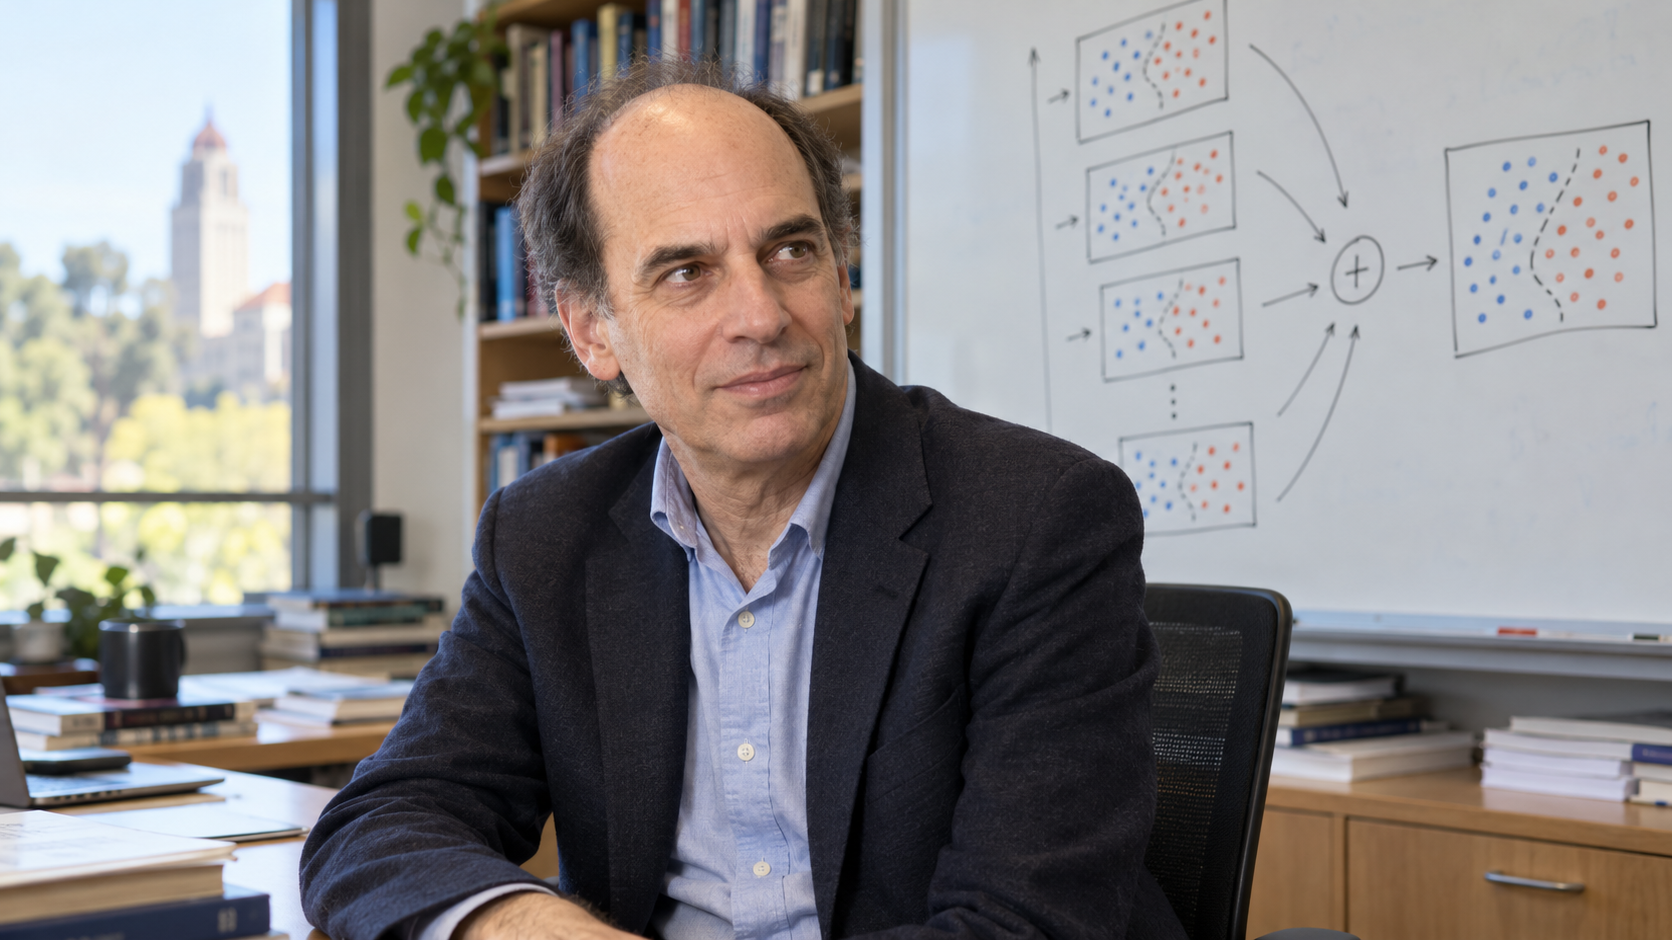
Yoav Freund and Robert Schapire developed a decision-theoretic framework for repeated prediction and used it to derive AdaBoost. The algorithm trains a sequence of weak learners while increasing attention to examples the current ensemble handles poorly. It then combines the learners through weighted voting. The work transformed a theoretical question—whether weak learning could become strong learning—into a practical method with broad influence. The original wording matters because it fixes the claim to a particular experiment, method, and moment instead of the larger mythology that later formed around it.
Boosting makes error informative. Instead of training independent models and averaging them, AdaBoost changes the distribution of attention after each round. Later learners concentrate on difficult cases, and their contributions are weighted according to performance. The ensemble can construct a complex decision rule from simple components. Its success revealed that the training process around a learner may matter as much as the learner’s standalone sophistication. Separating the method from the marketing makes the insight stronger, because readers can see exactly which capability improved and which judgments remain human responsibilities.
Boosted trees are widely used for ranking, fraud detection, risk modeling, and structured-data prediction. Modern systems add regularization, efficient optimization, and tools for managing missing values, but the iterative focus on residual mistakes remains recognizable. Teams should compare boosted models with simpler alternatives and examine whether gains come from legitimate signal, leakage, or features that act as proxies for sensitive information. The practical test is not whether a demonstration looks impressive, but whether the approach remains reliable under ordinary constraints, unusual cases, and changing environments.
Hard examples are not always informative examples. They may be mislabeled, anomalous, adversarial, or drawn from a group poorly represented in the data. Repeatedly increasing their weight can improve learning or amplify noise. Developers should investigate error clusters, validate labels, cap harmful influence when justified, and test performance under shifts. A procedure that learns from mistakes still needs judgment about what those mistakes mean. Technical success is incomplete when costs are hidden or errors fall disproportionately on people with the least power to contest them. Governance belongs in the design. Freund and Schapire showed that modest learners could become powerful through an adaptive sequence. The continuing responsibility is to make sure attention is directed toward real signal rather than reinforced error. Its legacy is most useful as a standard for careful inquiry: build boldly, measure honestly, and keep the people affected by the system in view. Readers can apply that standard by asking which evidence supports the claim, which conditions bound it, and who remains accountable when a system behaves differently in practice.
AdaBoost trains learners sequentially and gives more attention to examples the current ensemble misclassifies.
Weighted voting then combines the learners into a stronger decision rule.
A simple learner can contribute to a sophisticated model when each round responds to earlier failures.
The procedure shows that coordination among models can be as important as complexity inside one model.
Frequently misclassified examples may reveal useful boundaries, but they may also be noisy, mislabeled, or unrepresentative.
Error analysis and label review are necessary before repeated attention turns data problems into confident predictions.
Explore more "Quotes of The Day"
Continue exploring how writers, thinkers, artists, and advocates have described the choices that shape an everyday life.