How Does Tokenization Work in Language Models?
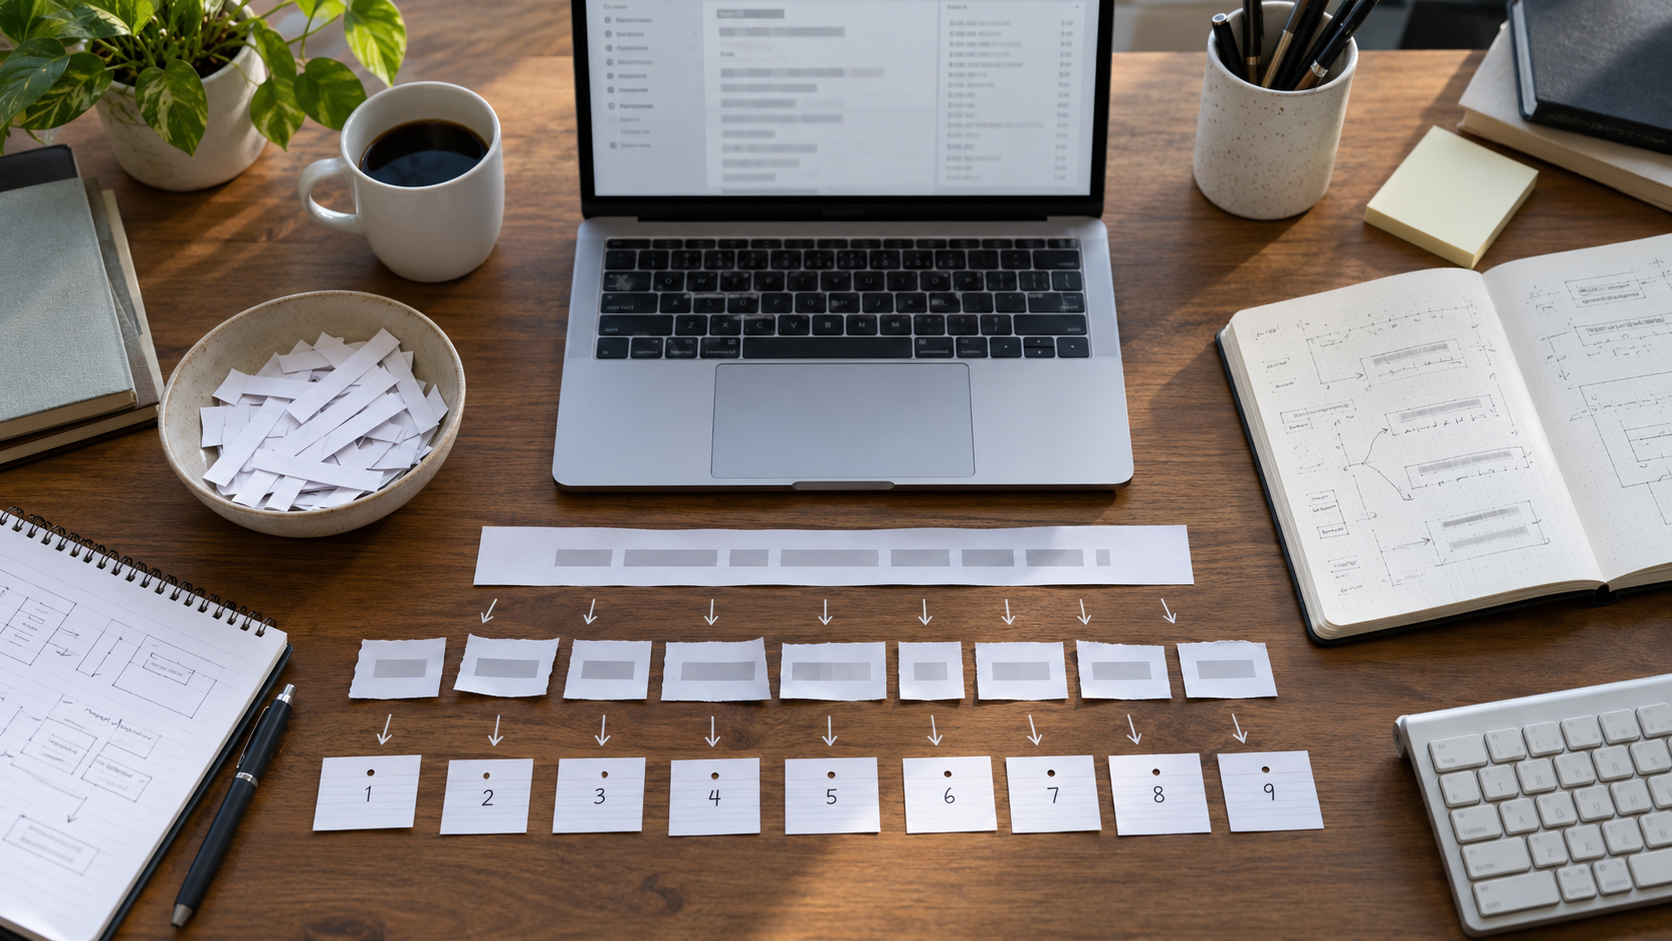
Tokenization converts text into model-readable units and numeric IDs before a language model processes or generates words.

Don't Just Read it – Explore It
Tokenization converts text into model-readable units and numeric IDs before a language model processes or generates words.
AI inference is the stage when a trained model receives new input and computes a prediction, classification, or generated response.
Fine-tuning continues training a pretrained AI model on a smaller, focused dataset to shape its behavior for a particular task or domain.
AI hallucinations are confident-sounding outputs that are false, unsupported, or inconsistent with the available evidence.
Gradient accumulation adds gradients from several smaller microbatches before updating model weights, approximating a larger batch with less memory.
Typical sampling selects next tokens from a set whose information content is close to the model’s expected uncertainty at that step.
Sequence packing combines multiple short training examples into fuller fixed-length batches so less computation is wasted on padding tokens.
Grammar-constrained generation permits only token sequences that can still form a valid string under a formal grammar.
Constrained decoding limits which next tokens a model may choose so the generated sequence follows required words, formats, or logical conditions.
Contrastive search balances a token’s probability with a penalty for hidden-state similarity that can signal repetitive or degenerate continuation.
BM25 is a lexical ranking function that scores documents using query-term frequency, term rarity, and document-length normalization.
Contrastive decoding chooses tokens by comparing a stronger language model with a weaker model and favoring options that reflect the stronger model’s expertise.