

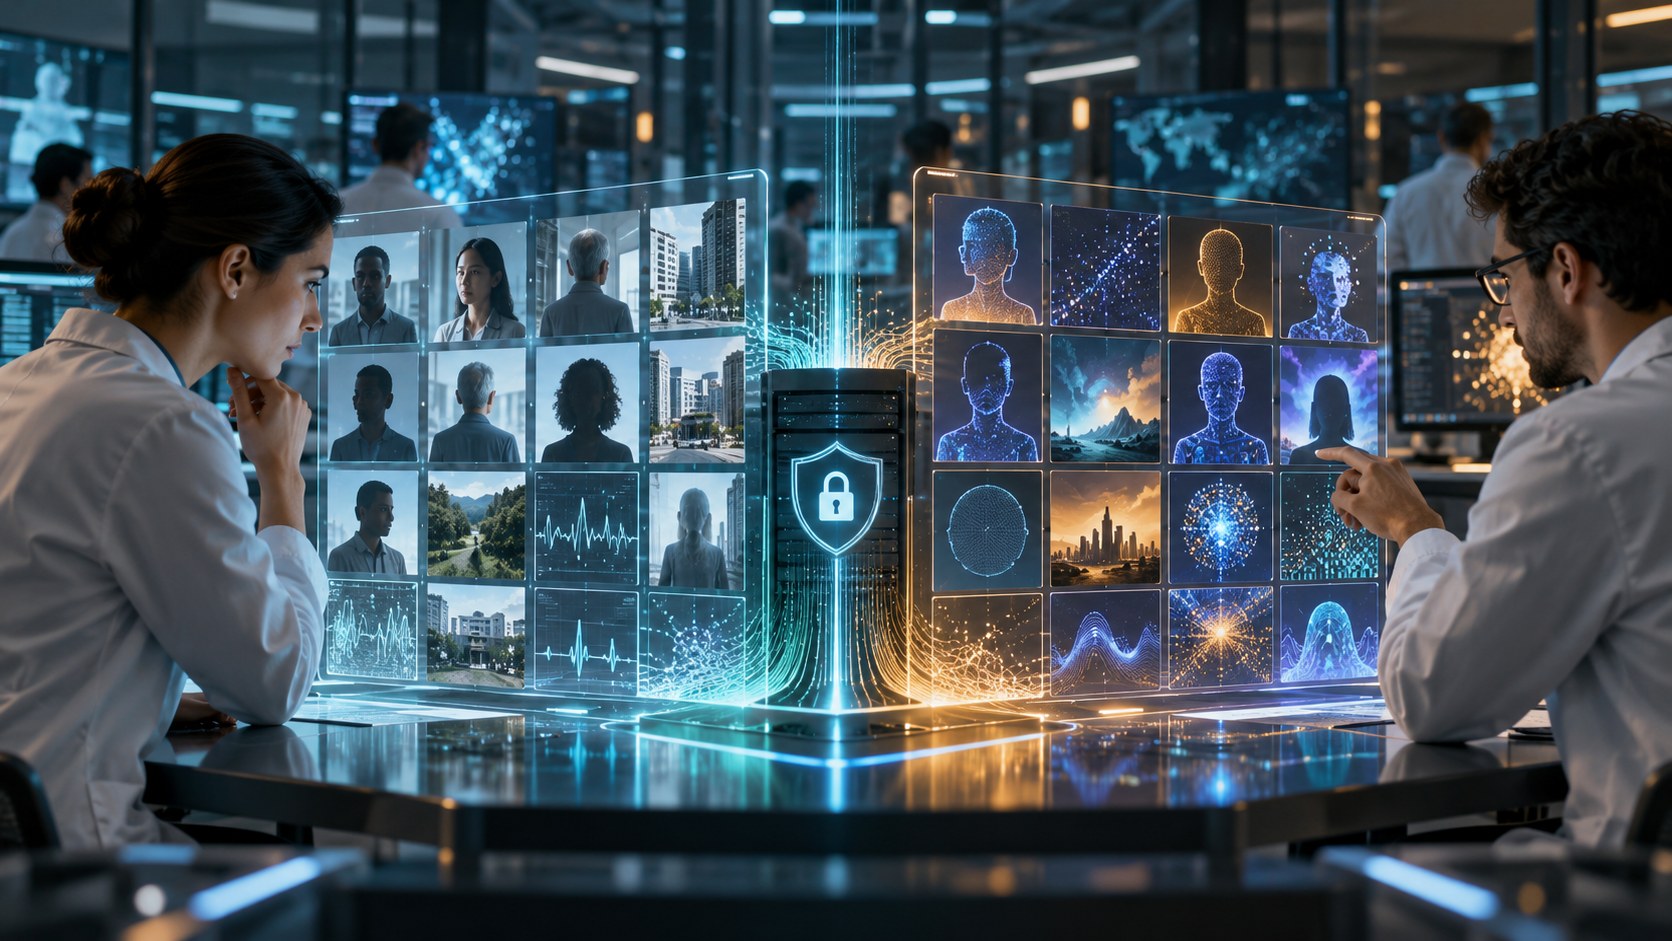
Synthetic Data Explainer
Synthetic data is artificially generated information created to reproduce selected patterns or properties of real data. It can take the form of tables, images, text, audio, simulations, or sensor readings. Synthetic records may be produced with statistical models, simulators, procedural rules, or generative AI.
Teams use synthetic data to supplement scarce examples, create rare or dangerous scenarios, test software, balance a dataset, or share information with less direct exposure of original records. In robotics and autonomous systems, simulation can provide large numbers of varied situations before real-world testing.
A synthetic dataset is useful only for the properties it preserves. If the generator misses an important correlation or rare group, a model trained on the result may fail in deployment. Artificial examples can also amplify the biases or mistakes in the source data and model.
Synthetic does not automatically mean anonymous. A generator can reveal information about its training data, and realistic records may still be mistaken for real ones. Privacy protection should be measured explicitly; differentially private generation can provide a formal guarantee, but often with a tradeoff in utility.
Synthetic data is artificially generated information designed to reproduce selected properties of real data without being a direct copy.
Key terms include synthetic data, simulator, generative model, utility, fidelity, privacy, re-identification, differential privacy and rare event.
<a href="https://csrc.nist.gov/pubs/sp/800/188/final" target="_blank" rel="noopener noreferrer">NIST SP 800-188: De-Identifying Government Datasets</a> and <a href="https://www.nist.gov/blogs/cybersecurity-insights/differentially-private-synthetic-data" target="_blank" rel="noopener noreferrer">NIST: Differentially Private Synthetic Data</a> provide the primary references for this explainer.
Synthetic examples can expand coverage, represent rare conditions, support testing, and reduce direct handling of sensitive records.
The generation method should be chosen for the downstream task, because no synthetic dataset preserves every property of the original.
A generator can reproduce bias, omit minority cases, or leak information learned from real people. Visual realism is not proof of statistical fidelity.
Evaluate utility and privacy separately, label synthetic content, document the process, and test models on appropriate real-world data.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.