

ZeRO Optimization Explainer
ZeRO, short for Zero Redundancy Optimizer, reduces memory used during distributed training. Ordinary data-parallel workers keep full copies of model parameters, gradients, and optimizer states even though much of that information is redundant across replicas.
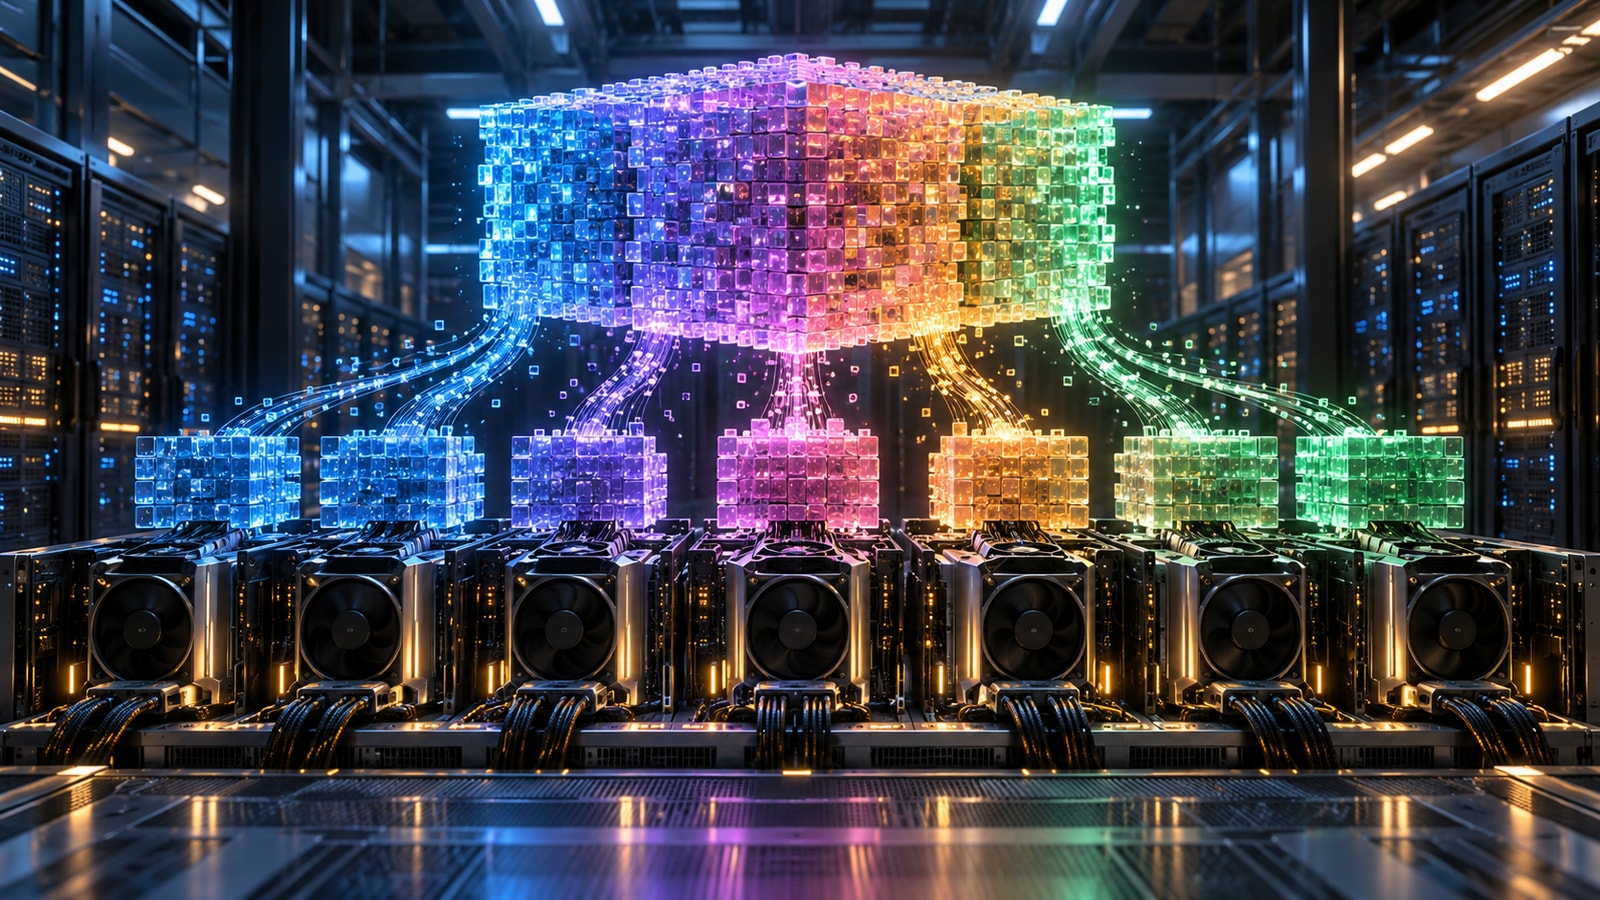
ZeRO partitions those states across workers. Successive stages shard optimizer states, then gradients, and finally parameters. When a worker needs a missing shard for computation, collective communication gathers it temporarily.
The method allows much larger models or batches to fit on the same accelerator cluster. Related systems can offload states to CPU memory or storage and combine sharding with tensor and pipeline parallelism.
Memory savings increase communication and implementation complexity. Offloading can shift the bottleneck to interconnects or storage. Evaluation should cover throughput, peak memory, network traffic, hardware cost, checkpointing, resilience, and convergence quality.
ZeRO optimization removes redundant training-state copies by partitioning optimizer states, gradients, and parameters across data-parallel workers.
Key terms include ZeRO, redundancy, optimizer state, gradient, parameter, shard, all-gather, reduce-scatter, offloading and distributed training.
Each device stores only a partition of states that would otherwise be fully replicated.
Collective operations assemble the needed pieces during computation.
Deeper sharding lowers local memory while increasing coordination and data transfer.
Offloading adds capacity but can introduce CPU, network, or storage bottlenecks.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.