

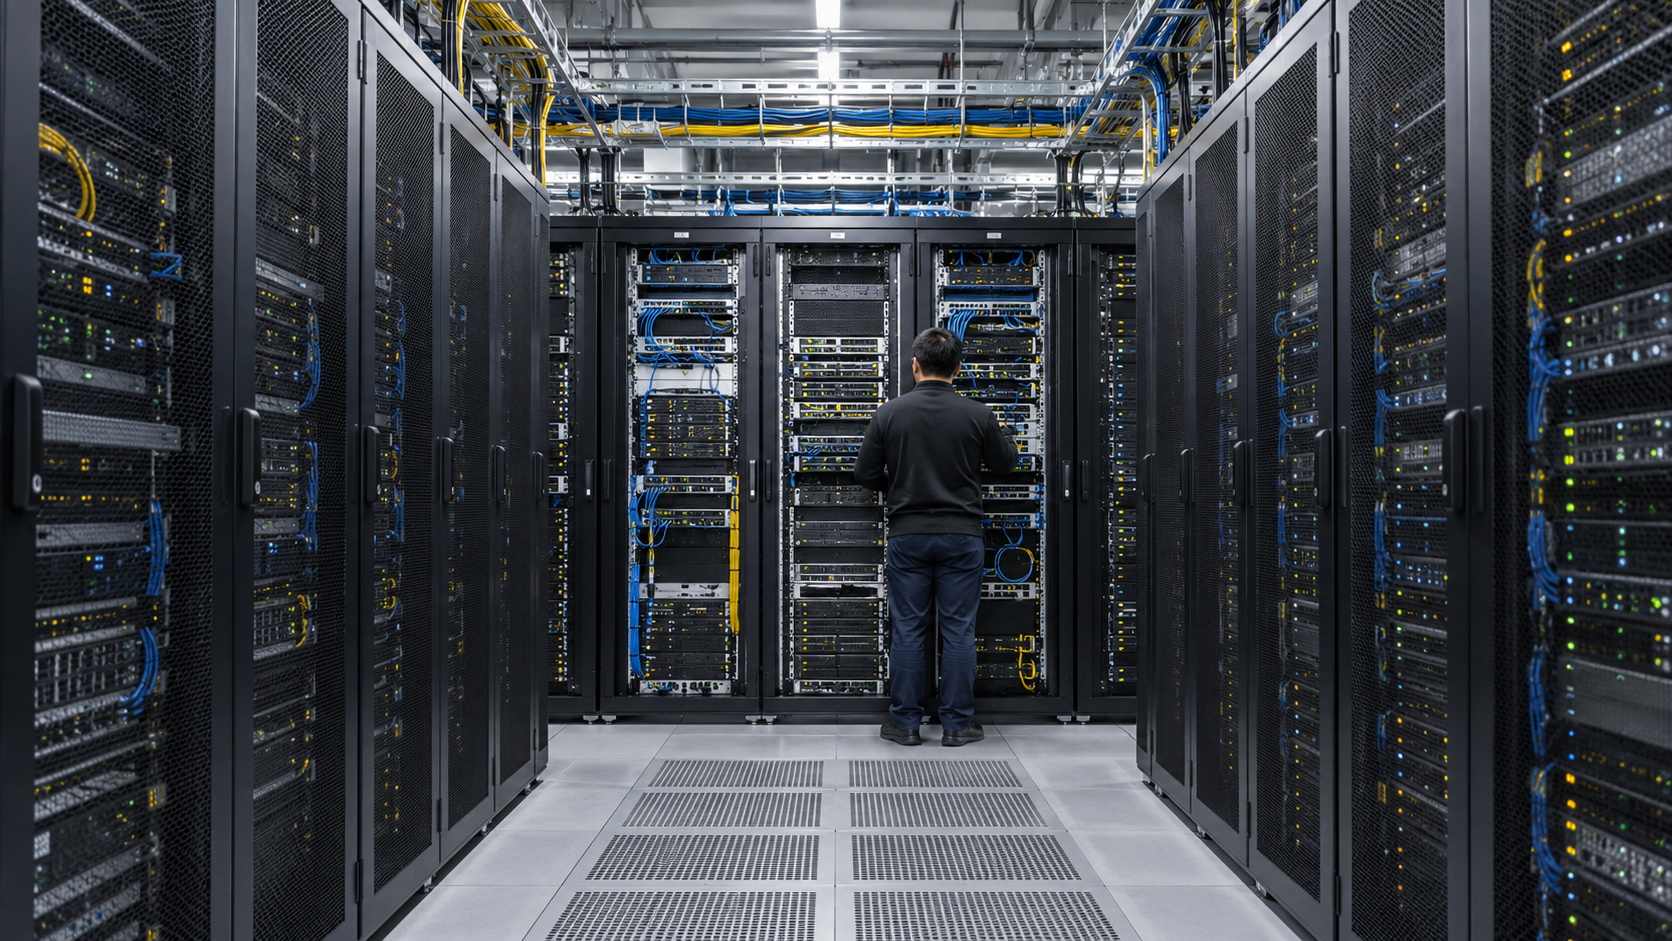
Cloud computing is a way to obtain computing resources—such as processing, storage, databases, networking, or applications—over a network from a shared pool that can be provisioned and released as demand changes. The word cloud does not mean the work happens in the air. It happens in physical data centers filled with servers, storage systems, switches, power equipment, and cooling infrastructure. The defining difference is how customers request and consume those resources: capacity is available through standardized services with much less direct handling of individual machines.
A cloud provider combines large amounts of hardware and uses virtualization, containers, orchestration, and software-defined networking to divide and assign capacity among customers. A customer may create a virtual machine, allocate object storage, or deploy an application through a console or programming interface. Automation selects suitable hardware, configures networking and access, and records usage. If demand rises, the service can add instances or capacity; when demand falls, it can release them. Pooling improves utilization because the same underlying facility serves many workloads with logical isolation.
Service models describe where the provider’s responsibility ends. With infrastructure as a service, the provider supplies foundational computing, storage, and networking while the customer manages operating systems, applications, and much of the security configuration. Platform as a service also manages more of the runtime and deployment environment. Software as a service delivers a finished application accessed through a browser, mobile app, or interface. These categories are useful guides, but real products often combine features, so contracts and technical documentation matter more than a marketing label.
Deployment models describe who uses and controls the environment. A public cloud offers shared provider infrastructure to many customers. A private cloud applies cloud-style automation and pooling for one organization. Hybrid designs connect private systems with public services, while multi-cloud strategies use services from more than one provider. Data can still reside in a specific facility and legal jurisdiction, even when users do not manage the hardware. Organizations choose regions, redundancy, and backup arrangements to meet performance, resilience, privacy, and regulatory needs.
Cloud systems can improve flexibility, global reach, and access to specialized services without requiring every customer to build a data center. They also change costs and risks. Usage-based billing can be efficient but unpredictable when resources are left running or data transfer grows. Outages at a provider can affect many customers at once. Misconfigured storage or identity permissions can expose information even when the provider’s infrastructure is secure. Moving a workload can be difficult when it depends heavily on proprietary databases, interfaces, or operational tools.
Security follows a shared-responsibility model. The provider protects facilities and the portions of the service it operates, while the customer remains responsible for its data, identities, configurations, and whatever software layers it controls. The exact boundary changes by service model. Strong authentication, least-privilege access, encryption, logging, tested backups, and cost monitoring remain necessary. Cloud computing is therefore not simply someone else’s computer; it is a managed delivery model built from real computers, extensive automation, measured use, and an explicit division of operational control. Availability also depends on architecture rather than the provider name alone. Deploying copies across independent failure zones can protect against a single facility problem, while using several regions may address larger outages at added cost and complexity. Customers must test restoration instead of assuming a synchronized copy is a backup. Automation can reproduce infrastructure consistently, but a faulty template can reproduce the same error everywhere. Good cloud operations combine repeatable configuration with review, monitoring, and deliberate recovery design. Capacity planning still matters: automatic scaling needs limits, health checks, and tested dependencies, because adding compute instances cannot fix a bottleneck in a database, identity service, or external network connection.
It remains on physical storage systems in provider data centers, usually within customer-selected regions or locations defined by the service.
SaaS provides a finished application, while IaaS provides foundational computing resources that leave the customer responsible for more software layers.
No. Responsibility is shared, and customers still control identities, data, permissions, configurations, and the software layers assigned to them.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.