

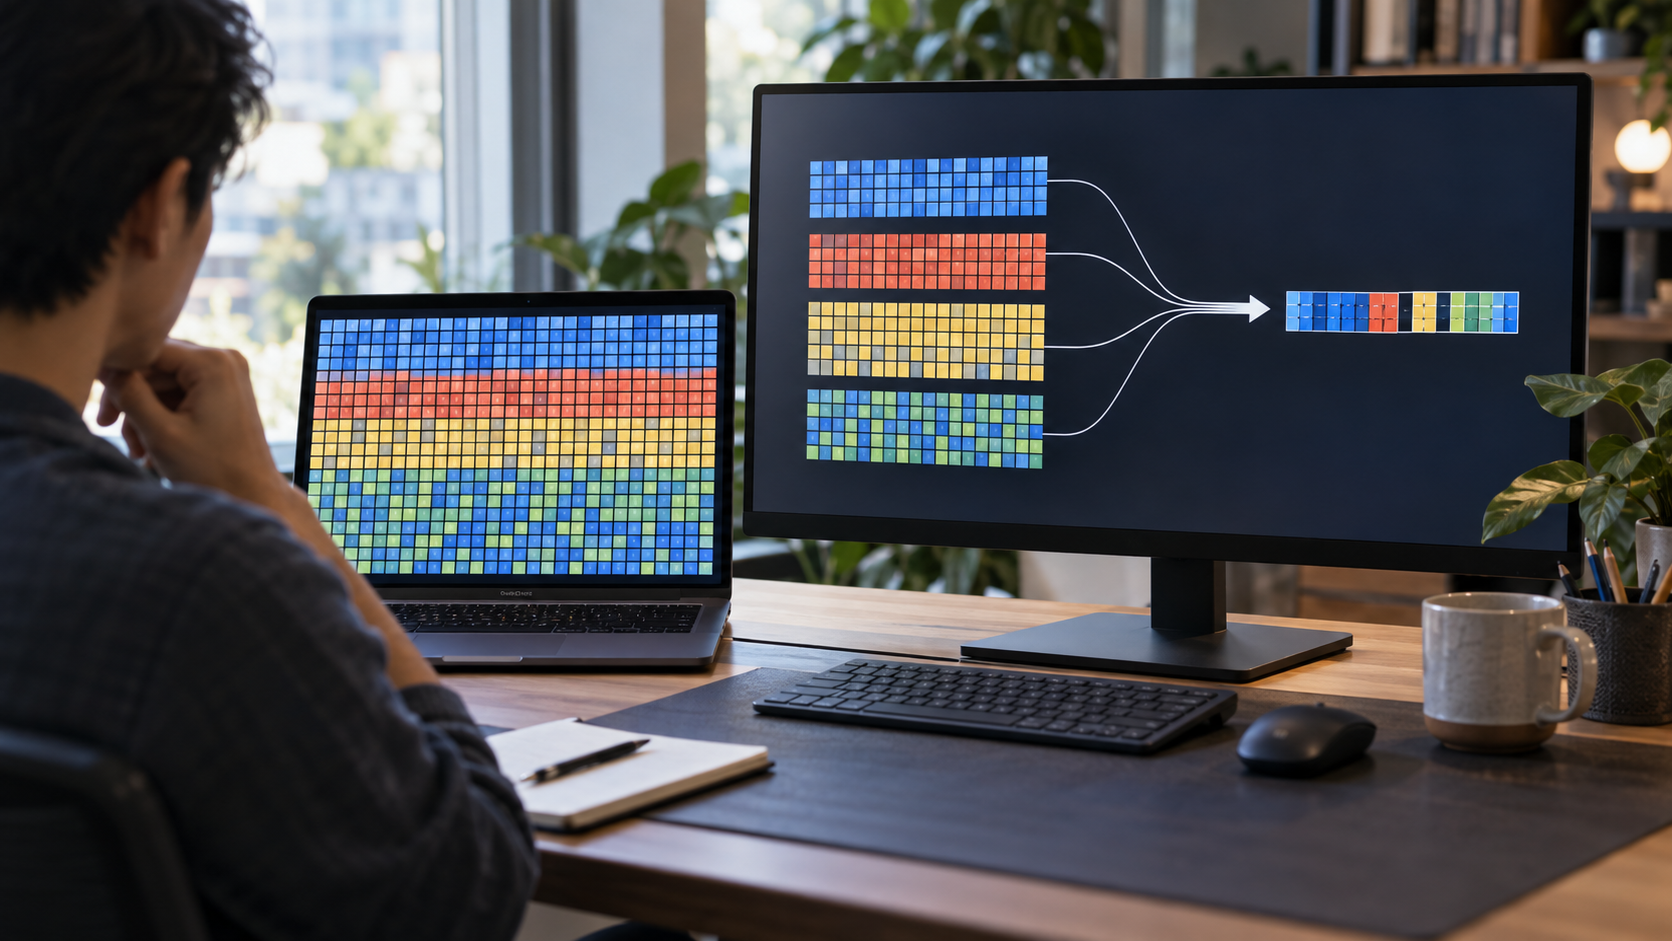
Data compression represents information using fewer bits so it requires less storage space or transmission time. A compressor looks for structure that can be encoded more efficiently than the original representation, and a decompressor applies the agreed rules to reconstruct usable data. Compression does not physically squeeze a file, and it cannot make every possible input smaller. Some data contains abundant repetition or predictable patterns, while data that is already compressed or nearly random may stay the same size or even grow slightly because the format adds headers and bookkeeping.
Lossless compression preserves every original bit. Text documents, program files, databases, and archives usually need this property because a single altered character or instruction can change meaning. Many lossless schemes replace repeated sequences with shorter references, build dictionaries of common patterns, or assign shorter codes to frequently occurring symbols. The DEFLATE format, for example, combines backward references related to LZ77 with Huffman coding. Decompression reads the codes and references in order, rebuilding the exact byte sequence without needing a separate copy of the original dictionary.
Lossy compression discards information judged less important to human perception or the intended use. Image encoders may represent smooth color changes compactly and reduce fine detail, while audio encoders can remove signals that are masked by stronger nearby sounds. Video compression also predicts blocks from earlier or later frames and stores changes rather than complete pictures repeatedly. The encoder controls a rate or quality target, and the decoder reconstructs an approximation. Lossy methods can achieve much smaller files, but repeated re-encoding may accumulate visible or audible damage.
Compression works best when the method matches the data. Natural photographs, screen captures, music, speech, source code, and sensor streams have different statistical patterns and quality requirements. A format also defines metadata, block structure, checksums, and rules a compatible decoder must follow. The algorithm may trade processing time and memory for a smaller result. A higher compression setting often searches more alternatives, which can slow encoding without changing how quickly every decoder operates. Hardware support and streaming needs can influence the practical choice as much as size.
The compression ratio compares original size with compressed size, but it is not a complete measure of success. For lossy media, visual or listening quality matters. For network services, latency and processor use may matter more than a few saved bytes. Compressing encrypted data is generally ineffective because strong encryption removes visible patterns, so compression must usually occur first. Compressing secrets together with attacker-controlled data can also create side channels: changes in output length may reveal whether guesses share patterns with protected information, which is why some secure protocols limit such combinations.
File extensions identify containers or formats, not a universal compression behavior. An archive may hold several files and use one of several algorithms, while some media formats support multiple encodings. Decompression also requires caution because a tiny malicious archive can expand into enormous output or exploit a decoder bug. Systems enforce size limits and update parsing libraries to manage those risks. The essential idea is that compression exploits predictability. Lossless methods preserve the exact original; lossy methods accept controlled information loss; and both must balance size, quality, speed, memory, compatibility, and security. Streaming compression works in blocks so a sender does not need the entire file before producing output. Smaller blocks reduce memory and recovery delays but may miss patterns spread far apart, lowering the compression ratio. Formats often include checkpoints or independently decodable sections to support seeking and error recovery. A damaged bit can otherwise confuse later codes and corrupt more than one symbol. Checksums can detect damage, but they do not necessarily repair it, so transport and storage protections still matter.
No. Already compressed or highly unpredictable data may not shrink and can grow slightly because the compressed format adds overhead.
Lossless compression reconstructs every original bit, while lossy compression discards selected information to achieve greater size reduction.
Encryption removes predictable patterns that compression relies on, so encrypted data normally offers little opportunity for additional compression.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.