What Is Structured Output in AI?
Structured output makes a model answer in a predefined machine-readable shape, such as a JSON object with required fields and value types.

Don't Just Read it – Explore It
Structured output makes a model answer in a predefined machine-readable shape, such as a JSON object with required fields and value types.
Function calling lets an AI model request a named external tool with structured arguments instead of pretending to perform the action in ordinary prose.
ZeRO optimization removes redundant training-state copies by partitioning optimizer states, gradients, and parameters across data-parallel workers.
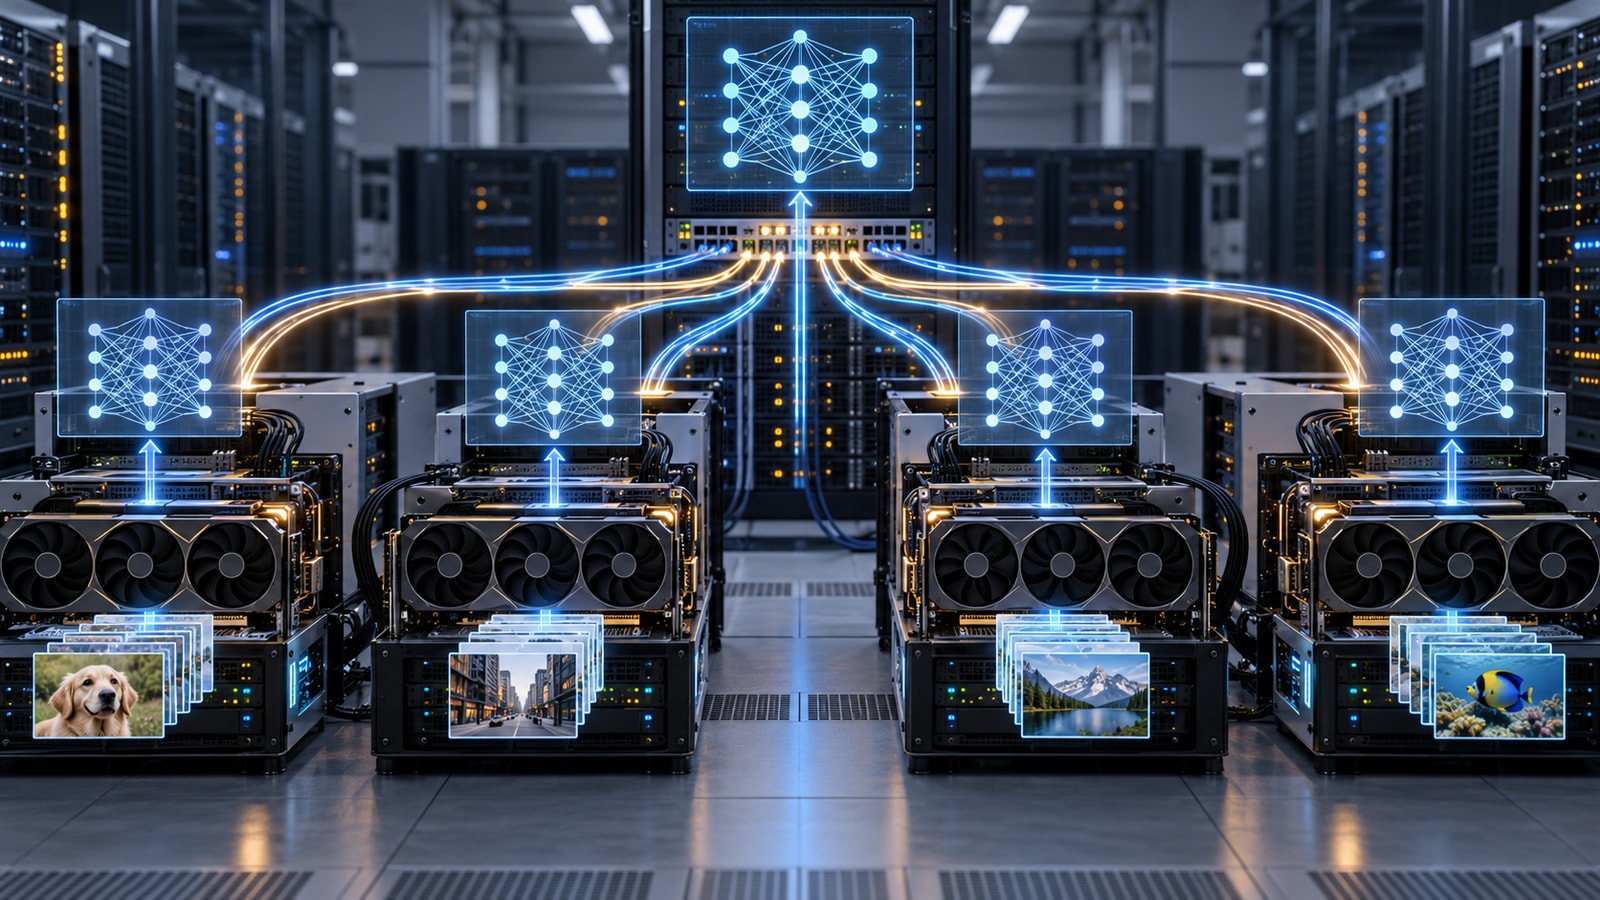
Data parallelism gives multiple devices copies of a model and trains each copy on a different portion of the batch before synchronizing updates.
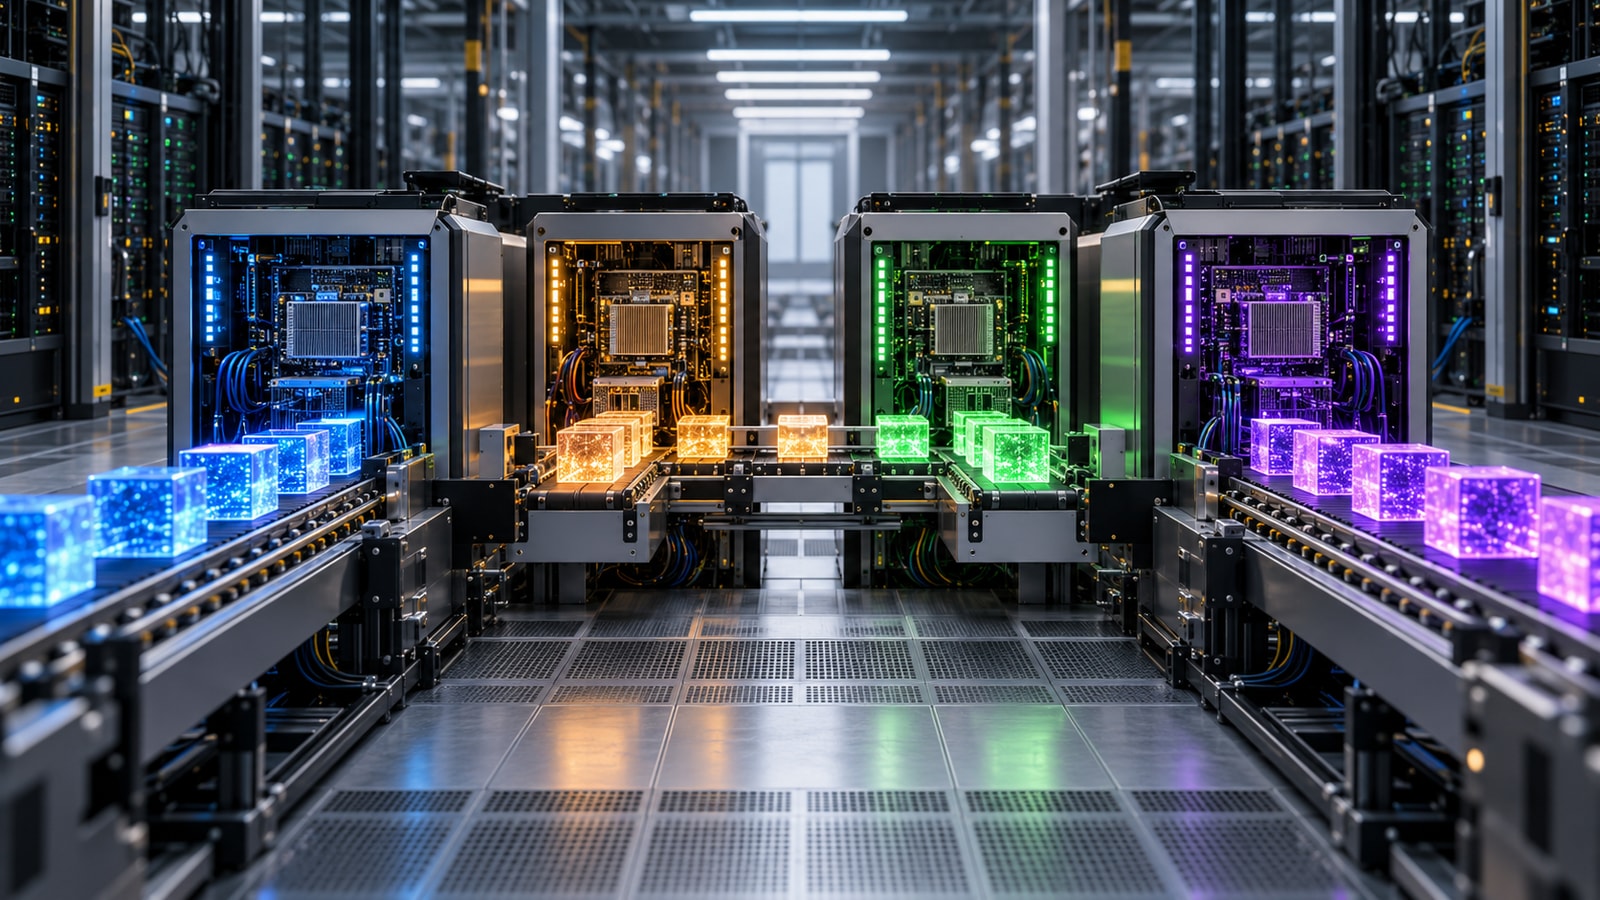
Pipeline parallelism places consecutive model stages on different devices and moves microbatches through them like an assembly line.
Continuous batching adds and removes generation requests between decoding steps so hardware stays busy despite different output lengths.
Tensor parallelism splits individual neural-network operations across devices so models or layers too large for one accelerator can run together.
Speculative decoding uses a faster draft model to propose several tokens that a larger model verifies in parallel without changing the output distribution.
A KV cache stores attention keys and values from earlier tokens so a language model does not recompute them for every new token.
Multi-query attention gives each attention head its own queries while all heads share one set of keys and values.
Grouped-query attention places query heads into groups that share key and value heads, balancing multi-head quality with multi-query efficiency.
ALiBi adds a distance-based bias to attention scores so farther tokens receive a larger penalty without learned positional embeddings.